Korea Advanced Institute of Science and Technology
Sep. 2024 — Feb. 2027 (expected)
M.S. Student, Kim Jaechul Graduate School of Artificial Intelligence
Music and Audio Computing Lab · Advisor: Prof. Juhan Nam
Hello! I'm an M.S. student at Kim Jaechul Graduate School of AI, KAIST (KAIST AI) in the Music and Audio Computing Lab, advised by Prof. Juhan Nam. I received a bachelor's degree in Computer Science from Yonsei University, where I worked on voice conversion with Prof. Hong-Goo Kang.
My research experience spans representation learning, controllable generation, and automated perceptual evaluation in speech. My broader goal is to build speech-centered multimodal AI that can perceive, represent, and generate cues beyond words across speech and other modalities, enabling more natural and affective human–AI interaction.
Research interests
🎓 I am actively looking for a Ph.D. position for Fall 2027.
Seoul, South Korea
01 / Updates
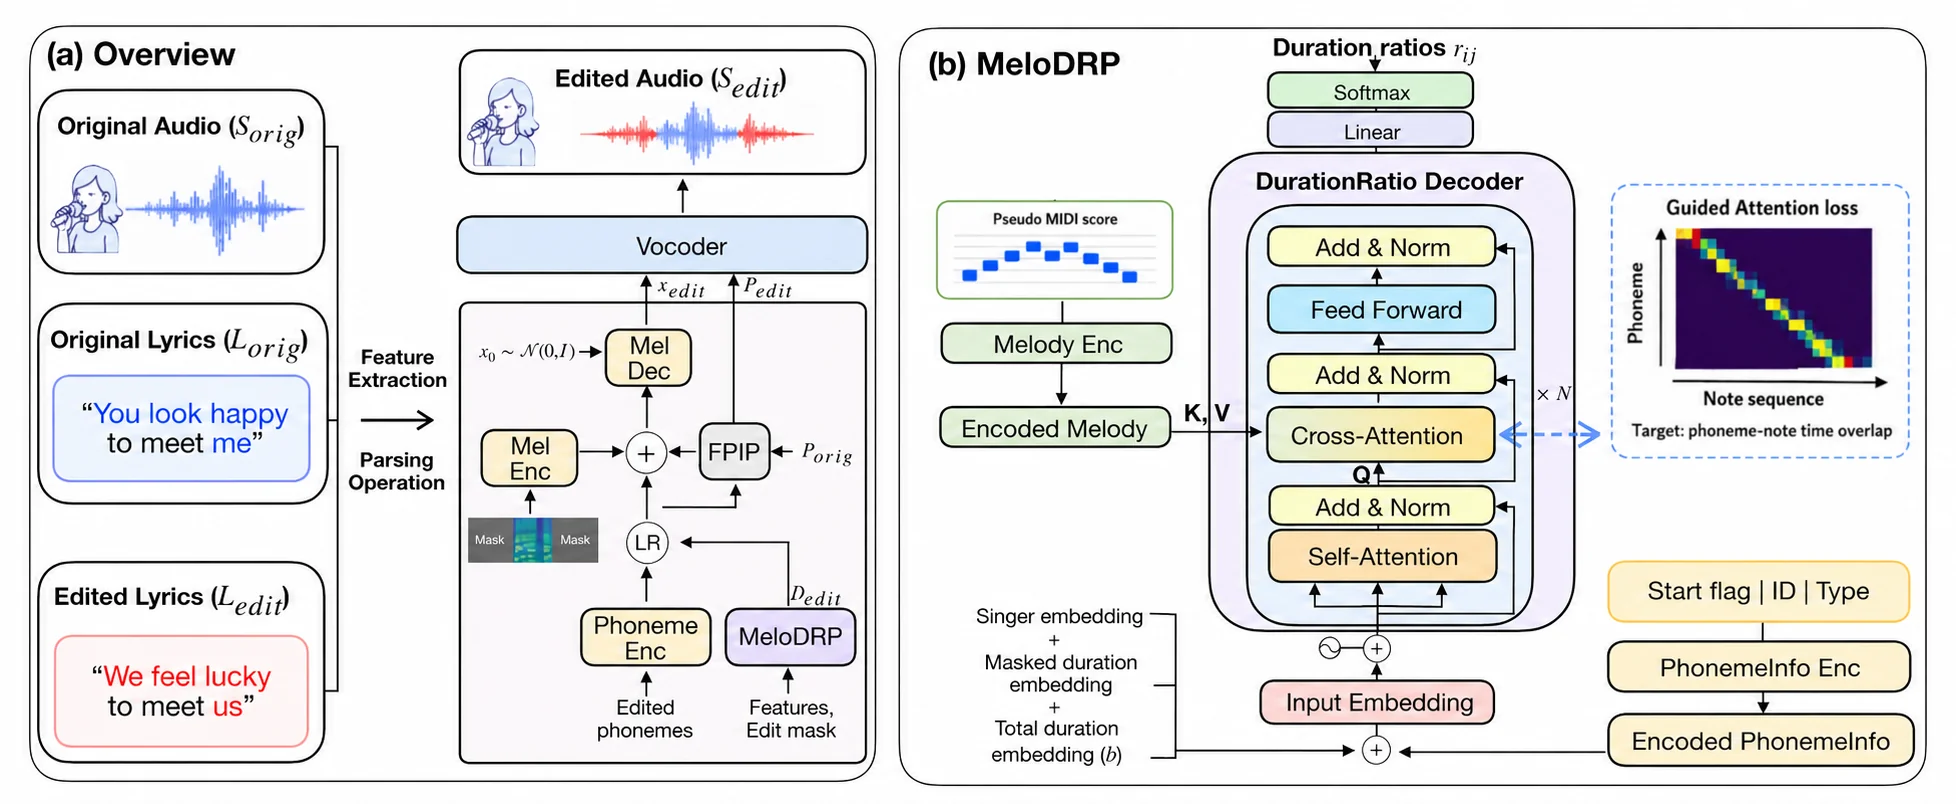
Presented MeloDISinger at the Interspeech 2026 poster session 🐨.
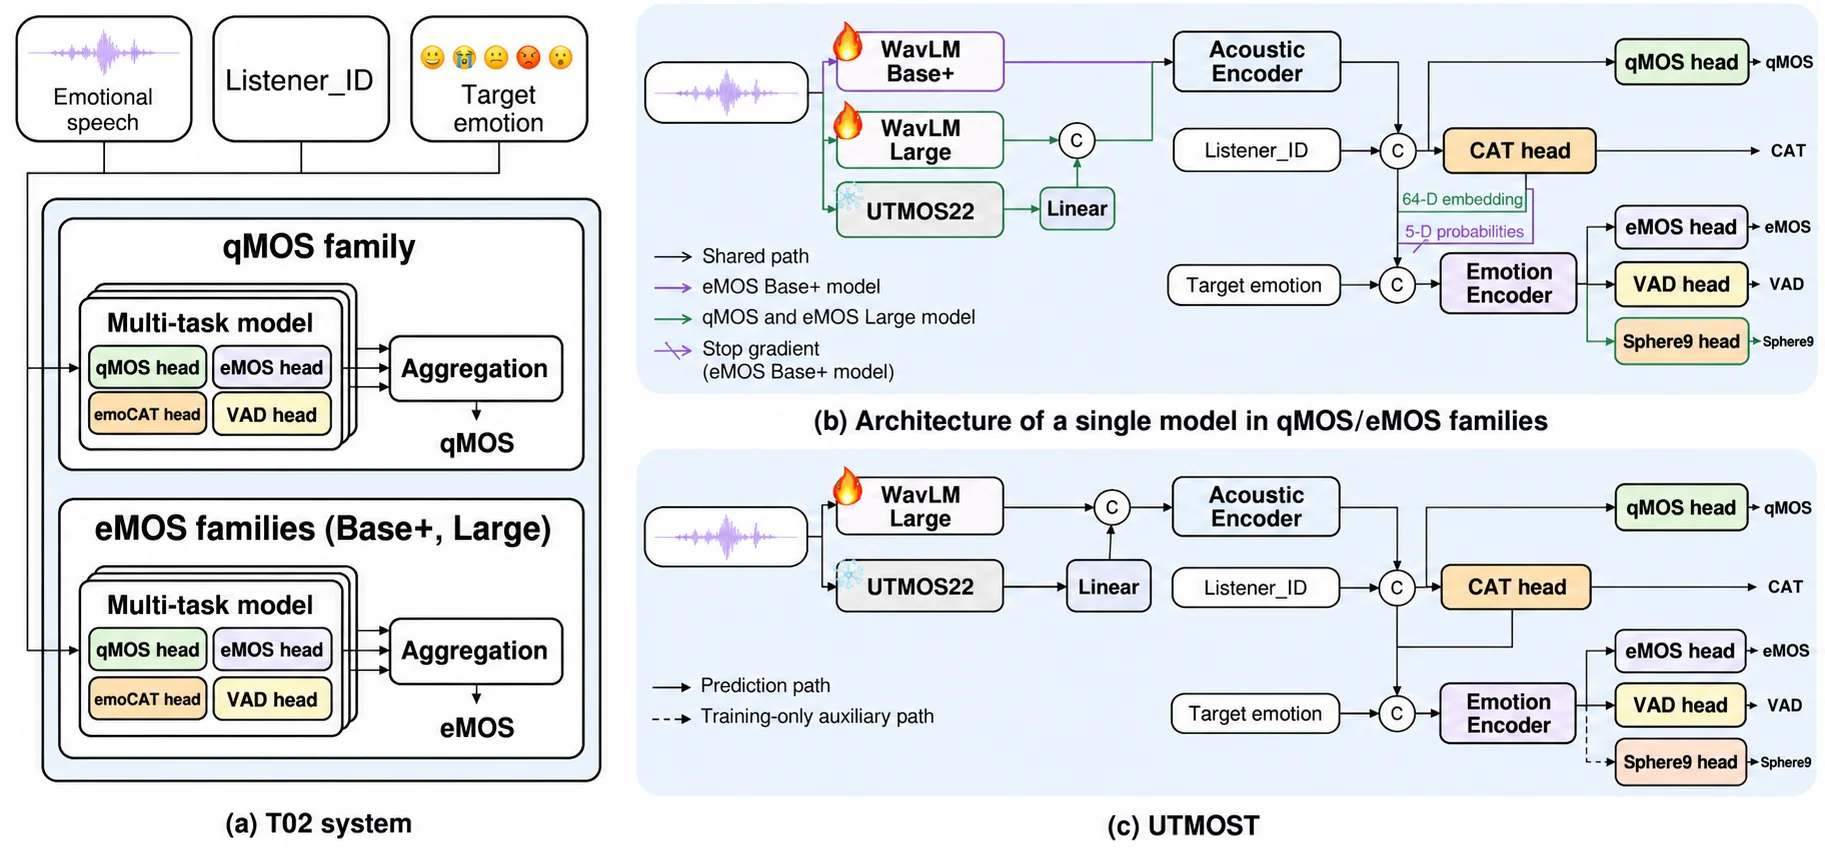
Our system ranked first in Track 2 of the VoiceMOS Challenge 2026 for predicting speech naturalness and emotion similarity in emotional TTS! 🥇.
Visited the Max Planck Institute for Empirical Aesthetics for a research stay to work on a survey of empathetic and conversational spoken language systems 🇩🇪.
Gave a research talk on MeloDISinger at the AIR Lab Seminar, University of Rochester 🇺🇸.
MeloDISinger, my first M.S. work on singing voice editing, was accepted to Interspeech 2026 🎉.
Received CAD 37K in government funding for research training and joined the University of Toronto as a visiting graduate student 🇨🇦.
Volunteered at ISMIR 2025 and had a great time meeting the MIR community 🎶.
Served as a student coordinator for the KSMI 2025 Founding Symposium 🇰🇷.
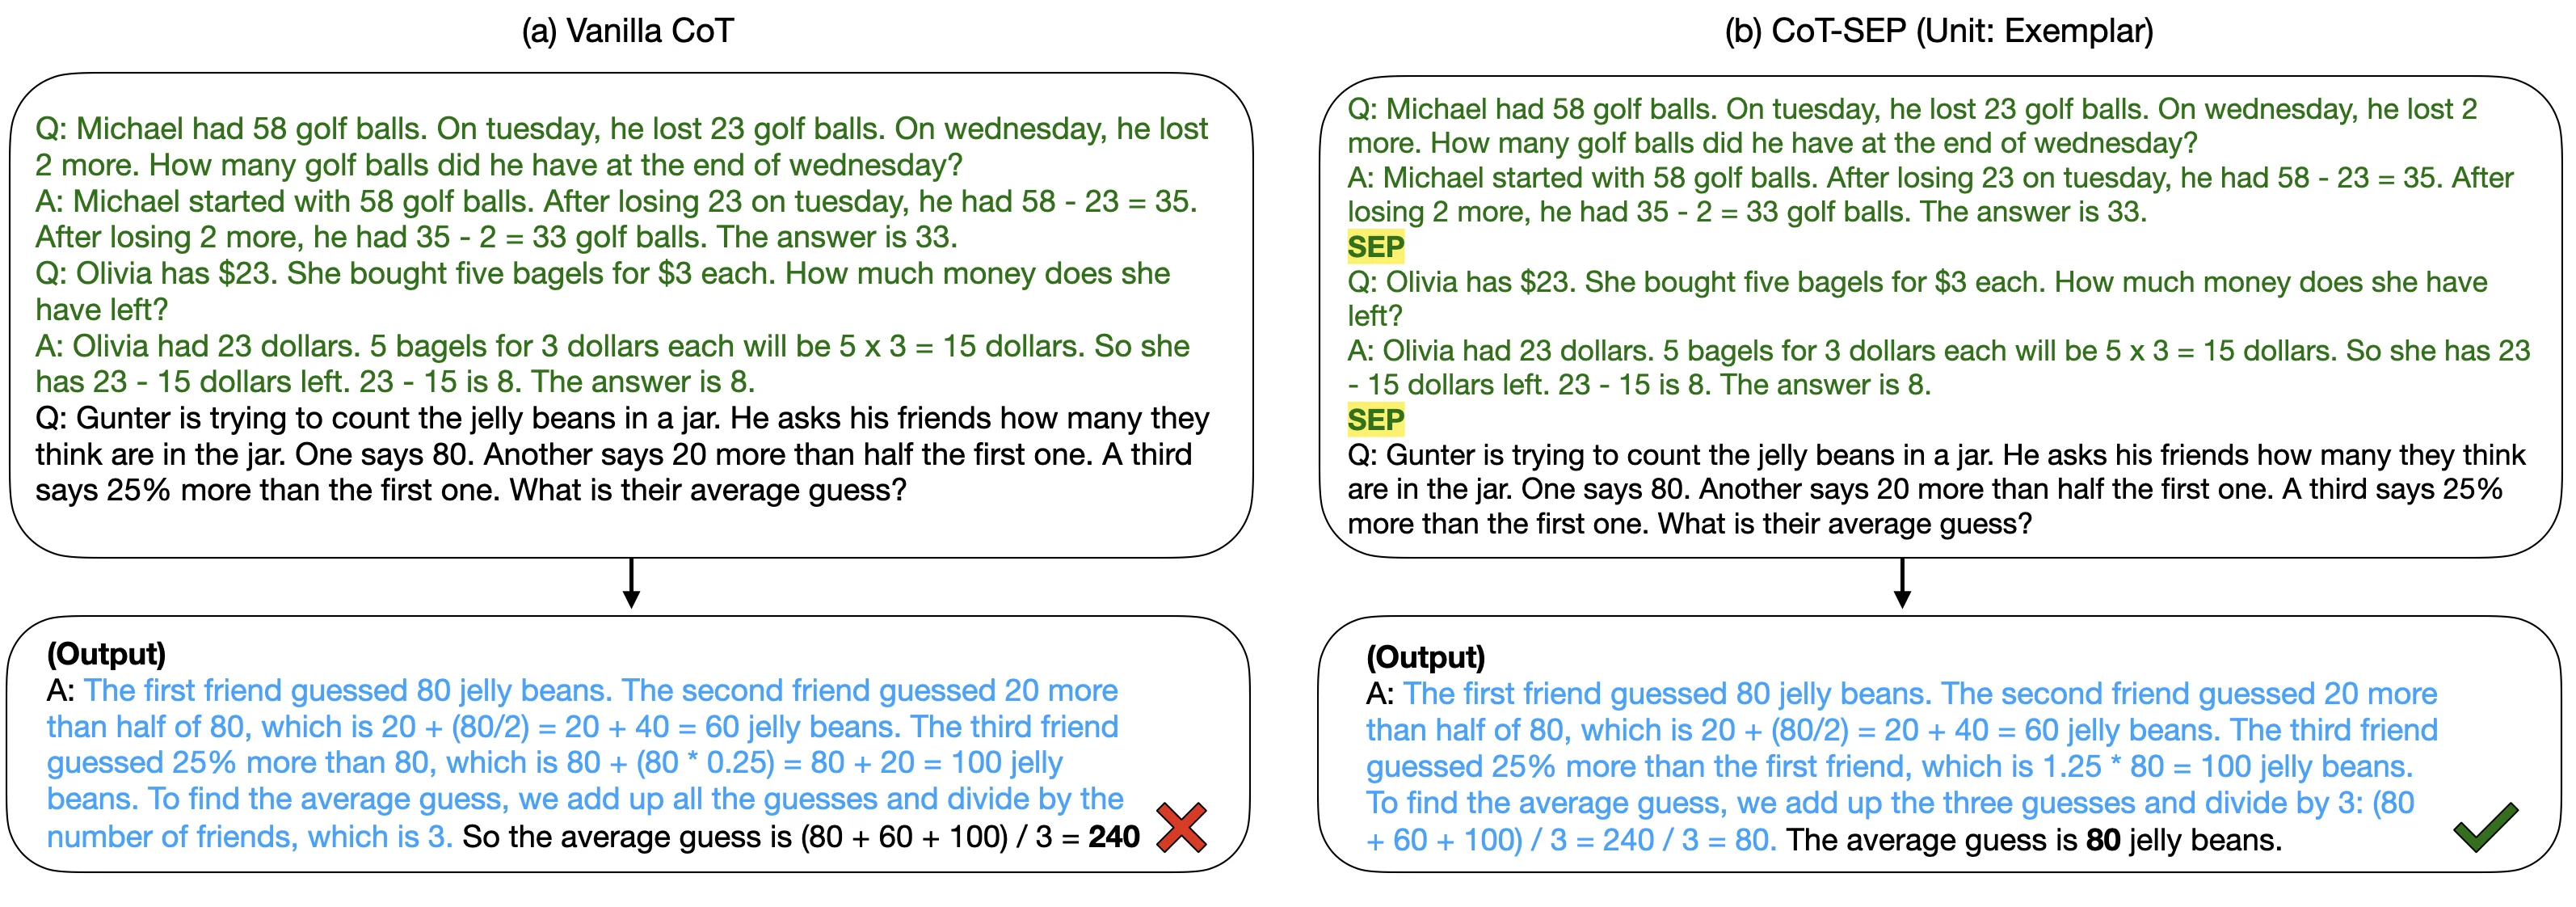
CoT-Sep, my first paper, was accepted for an oral presentation at IEEE FLLM 2024. 🎉
Started my M.S. at KAIST AI. 🎓
02 / Background
Sep. 2024 — Feb. 2027 (expected)
M.S. Student, Kim Jaechul Graduate School of Artificial Intelligence
Music and Audio Computing Lab · Advisor: Prof. Juhan Nam
Jan. 2026 — Jun. 2026
Visiting Graduate Research Student
CARTE-IITP industry research program with LG Electronics Toronto AI Lab
Mar. 2019 — Aug. 2024
B.S. in Computer Science
Overall GPA: 3.8/4.3 · CS GPA: 3.96/4.3

Jan. 2023 — Apr. 2023
Exchange Student, Computer Engineering
03 / Selected work
Under review